T
his is a comprehensive tutorial on using the Spark distributed machine learning framework to build a scalable ML data pipeline. I will cover the basic machine learning algorithms implemented in Spark MLlib library and through this tutorial, I will use the PySpark in python environment.

Machine learning is getting popular in solving real-world problems in almost every business domain. It helps solve the problems using the data which is often unstructured, noisy, and in huge size. With the increase in data sizes and various sources of data, solving machine learning problems using standard techniques pose a big challenge. Spark is a distributed processing engine using the MapReduce framework to solve problems related to big data and processing of it.
Spark framework has its own machine learning module called MLlib. In this article, I will use pyspark and spark MLlib to demonstrate the use of machine learning using distributed processing. Readers will be able to learn the below concept with real examples.
- Setting up Spark in the Google Colaboratory
- Machine Learning Basic Concepts
- Preprocessing and Data Transformation using Spark
- Spark Clustering with pyspark
- Classification with pyspark
- Regression methods with pyspark
A working google colab notebook will be provided to reproduce the results.
Since this article is a hands-on tutorial covering the transformations, classification, clustering, and regression using pyspark in one session, the length of the article is longer than my previous articles. One benefit is that you can go through the basic concepts and implementation in one go.
What is Apache Spark?
According to Apache Spark and Delta Lake Under the Hood
Apache Spark is a unified computing engine and a set of libraries for parallel data processing on computer clusters. As of the time this writing, Spark is the most actively developed open source engine for this task; making it the de facto tool for any developer or data scientist interested in big data. Spark supports multiple widely used programming languages (Python, Java, Scala and R), includes libraries for diverse tasks ranging from SQL to streaming and machine learning, and runs anywhere from a laptop to a cluster of thousands of servers. This makes it an easy system to start with and scale up to big data processing or incredibly large scale.

Setting up Spark 3.0.1 in the Google Colaboratory
As a first step, I configure the google colab runtime with spark installation. For details, readers may read my article Getting Started Spark 3.0.0 in Google Colab om medium.
We will install the below programs
- Java 8
- spark-3.0.1
- Hadoop3.2
- Findspark
you can install the LATEST version of Spark using the below set of commands.
# Run below commands
!apt-get install openjdk-8-jdk-headless -qq > /dev/null
!wget -q http://apache.osuosl.org/spark/spark-3.0.1/spark-3.0.1-bin-hadoop3.2.tgz
!tar xf spark-3.0.1-bin-hadoop3.2.tgz
!pip install -q findspark
Environment Variable
After installing the spark and Java, set the environment variables where Spark and Java are installed.
import os
os.environ["JAVA_HOME"] = "/usr/lib/jvm/java-8-openjdk-amd64"
os.environ["SPARK_HOME"] = "/content/spark-3.0.1-bin-hadoop3.2"
Spark Installation test
Let us test the installation of spark in our google colab environment.
import findspark
findspark.init()

from pyspark.sql import SparkSession

spark = SparkSession.builder.master("local[*]").getOrCreate()
# Test the spark
df = spark.createDataFrame([{"hello": "world"} for x in range(1000)])

df.show(3, False)/content/spark-3.0.1-bin-hadoop3.2/python/pyspark/sql/session.py:381: UserWarning: inferring schema from dict is deprecated,please use pyspark.sql.Row instead
  warnings.warn("inferring schema from dict is deprecated,"


+-----+
|hello|
+-----+
|world|
|world|
|world|
+-----+
only showing top 3 rows# make sure the version of pyspark
import pyspark
print(pyspark.__version__)3.0.1
Machine Learning
Once, we have set up the spark in google colab and made sure it is running with the correct version i.e. 3.0.1 in this case, we can start exploring the machine learning API developed on top of Spark. PySpark is a higher level Python API to use spark with python. For this tutorial, I assume the readers have a basic understanding of Machine Learning and SK-Learn for model building and training. Spark MLlib used the same fit and predict structure as in SK-Learn.
In order to reproduce the results, I have uploaded the data to my GitHub and can be accessed easily.
Learn by Doing: Use the colab notebook to run it yourself
Data Preparation and Transformations in Spark
This section covers the basic steps involved in transformations of input feature data into the format Machine Learning algorithms accept. We will be covering the transformations coming with the SparkML library. To understand or read more about the available spark transformations in 3.0.3, follow the below link.
Normalize Numeric Data
MinMaxScaler is one of the favorite classes shipped with most machine learning libraries. It scaled the data between 0 and 1.
from pyspark.ml.feature import MinMaxScaler
from pyspark.ml.linalg import Vectors# Create some dummy feature data
features_df = spark.createDataFrame([
    (1, Vectors.dense([10.0,10000.0,1.0]),),
    (2, Vectors.dense([20.0,30000.0,2.0]),),
    (3, Vectors.dense([30.0,40000.0,3.0]),),

],["id", "features"] )features_df.show()+---+------------------+
| id|          features|
+---+------------------+
|  1|[10.0,10000.0,1.0]|
|  2|[20.0,30000.0,2.0]|
|  3|[30.0,40000.0,3.0]|
+---+------------------+# Apply MinMaxScaler transformation
features_scaler = MinMaxScaler(inputCol = "features", outputCol = "sfeatures")
smodel = features_scaler.fit(features_df)
sfeatures_df = smodel.transform(features_df)sfeatures_df.show()+---+------------------+--------------------+
| id|          features|           sfeatures|
+---+------------------+--------------------+
|  1|[10.0,10000.0,1.0]|           (3,[],[])|
|  2|[20.0,30000.0,2.0]|[0.5,0.6666666666...|
|  3|[30.0,40000.0,3.0]|       [1.0,1.0,1.0]|
+---+------------------+--------------------+
Standardize Numeric Data
StandardScaler is another well-known class written with machine learning libraries. It normalizes the data between -1 and 1 and converts the data into bell-shaped data. You can demean the data and scale to some variance.
from pyspark.ml.feature import  StandardScaler
from pyspark.ml.linalg import Vectors# Create the dummy data
features_df = spark.createDataFrame([
    (1, Vectors.dense([10.0,10000.0,1.0]),),
    (2, Vectors.dense([20.0,30000.0,2.0]),),
    (3, Vectors.dense([30.0,40000.0,3.0]),),

],["id", "features"] )# Apply the StandardScaler model
features_stand_scaler = StandardScaler(inputCol = "features", outputCol = "sfeatures", withStd=True, withMean=True)
stmodel = features_stand_scaler.fit(features_df)
stand_sfeatures_df = stmodel.transform(features_df)stand_sfeatures_df.show()+---+------------------+--------------------+
| id|          features|           sfeatures|
+---+------------------+--------------------+
|  1|[10.0,10000.0,1.0]|[-1.0,-1.09108945...|
|  2|[20.0,30000.0,2.0]|[0.0,0.2182178902...|
|  3|[30.0,40000.0,3.0]|[1.0,0.8728715609...|
+---+------------------+--------------------+
Bucketize Numeric Data
The real data sets come with various ranges and sometimes it is advisable to transform the data into well-defined buckets before plugging into machine learning algorithms.
Bucketizer class is handy to transform the data into various buckets.
from pyspark.ml.feature import  Bucketizer
from pyspark.ml.linalg import Vectors# Define the splits for buckets
splits = [-float("inf"), -10, 0.0, 10, float("inf")]
b_data = [(-800.0,), (-10.5,), (-1.7,), (0.0,), (8.2,), (90.1,)]
b_df = spark.createDataFrame(b_data, ["features"])b_df.show()+--------+
|features|
+--------+
|  -800.0|
|   -10.5|
|    -1.7|
|     0.0|
|     8.2|
|    90.1|
+--------+# Transforming data into buckets
bucketizer = Bucketizer(splits=splits, inputCol= "features", outputCol="bfeatures")
bucketed_df = bucketizer.transform(b_df)bucketed_df.show()+--------+---------+
|features|bfeatures|
+--------+---------+
|  -800.0|      0.0|
|   -10.5|      0.0|
|    -1.7|      1.0|
|     0.0|      2.0|
|     8.2|      2.0|
|    90.1|      3.0|
+--------+---------+
Tokenize text Data
Natural Language Processing is one of the main applications of Machine learning. One of the first steps for NLP is tokenizing the text into words or token. We can utilize the Tokenizer class with SparkML to perform this task.
from pyspark.ml.feature import  Tokenizersentences_df = spark.createDataFrame([
    (1, "This is an introduction to sparkMlib"),
    (2, "Mlib incluse libraries fro classfication and regression"),
    (3, "It also incluses support for data piple lines"),

], ["id", "sentences"])sentences_df.show()+---+--------------------+
| id|           sentences|
+---+--------------------+
|  1|This is an introd...|
|  2|Mlib incluse libr...|
|  3|It also incluses ...|
+---+--------------------+sent_token = Tokenizer(inputCol = "sentences", outputCol = "words")
sent_tokenized_df = sent_token.transform(sentences_df)sent_tokenized_df.take(10)[Row(id=1, sentences='This is an introduction to sparkMlib', words=['this', 'is', 'an', 'introduction', 'to', 'sparkmlib']),
 Row(id=2, sentences='Mlib incluse libraries fro classfication and regression', words=['mlib', 'incluse', 'libraries', 'fro', 'classfication', 'and', 'regression']),
 Row(id=3, sentences='It also incluses support for data piple lines', words=['it', 'also', 'incluses', 'support', 'for', 'data', 'piple', 'lines'])]
TF-IDF
Term frequency-inverse document frequency (TF-IDF) is a feature vectorization method widely used in text mining to reflect the importance of a term to a document in the corpus. Using the above-tokenized data, Let us apply the TF-IDF
from pyspark.ml.feature import HashingTF, IDFhashingTF = HashingTF(inputCol = "words", outputCol = "rawfeatures", numFeatures = 20)
sent_fhTF_df = hashingTF.transform(sent_tokenized_df)sent_fhTF_df.take(1)[Row(id=1, sentences='This is an introduction to sparkMlib', words=['this', 'is', 'an', 'introduction', 'to', 'sparkmlib'], rawfeatures=SparseVector(20, {6: 2.0, 8: 1.0, 9: 1.0, 10: 1.0, 13: 1.0}))]idf = IDF(inputCol = "rawfeatures", outputCol = "idffeatures")
idfModel = idf.fit(sent_fhTF_df)
tfidf_df = idfModel.transform(sent_fhTF_df)tfidf_df.take(1)[Row(id=1, sentences='This is an introduction to sparkMlib', words=['this', 'is', 'an', 'introduction', 'to', 'sparkmlib'], rawfeatures=SparseVector(20, {6: 2.0, 8: 1.0, 9: 1.0, 10: 1.0, 13: 1.0}), idffeatures=SparseVector(20, {6: 0.5754, 8: 0.6931, 9: 0.0, 10: 0.6931, 13: 0.2877}))]
User can play with various transformations depending on the requirements of the problem in-hand.
Clustering Using PySpark
Clustering is a machine learning technique where the data is grouped into a reasonable number of classes using the input features. In this section, we study the basic application of clustering techniques using the spark ML framework.
from pyspark.ml.linalg import Vectors
from pyspark.ml.feature import VectorAssembler
from pyspark.ml.clustering import KMeans, BisectingKMeans
import glob# Downloading the clustering dataset
!wget -q 'https://raw.githubusercontent.com/amjadraza/blogs-data/master/spark_ml/clustering_dataset.csv'
Load the clustering data stored in csv format using spark
# Read the data.
clustering_file_name ='clustering_dataset.csv'
import pandas as pd
# df = pd.read_csv(clustering_file_name)
cluster_df = spark.read.csv(clustering_file_name, header=True,inferSchema=True)
Convert the tabular data into vectorized format using VectorAssembler
# Coverting the input data into features column
vectorAssembler = VectorAssembler(inputCols = ['col1', 'col2', 'col3'], outputCol = "features")
vcluster_df = vectorAssembler.transform(cluster_df)vcluster_df.show(10)+----+----+----+--------------+
|col1|col2|col3|      features|
+----+----+----+--------------+
|   7|   4|   1| [7.0,4.0,1.0]|
|   7|   7|   9| [7.0,7.0,9.0]|
|   7|   9|   6| [7.0,9.0,6.0]|
|   1|   6|   5| [1.0,6.0,5.0]|
|   6|   7|   7| [6.0,7.0,7.0]|
|   7|   9|   4| [7.0,9.0,4.0]|
|   7|  10|   6|[7.0,10.0,6.0]|
|   7|   8|   2| [7.0,8.0,2.0]|
|   8|   3|   8| [8.0,3.0,8.0]|
|   4|  10|   5|[4.0,10.0,5.0]|
+----+----+----+--------------+
only showing top 10 rows
Once the data is prepared into the format MLlib can use for models, now we can define and train the clustering algorithm such as K-Means. We can define the number of clusters and initialize the seed as done below.
# Applying the k-means algorithm
kmeans = KMeans().setK(3)
kmeans = kmeans.setSeed(1)
kmodel = kmeans.fit(vcluster_df)
After training has been finished, let us print the centers.
centers = kmodel.clusterCenters()
print("The location of centers: {}".format(centers))The location of centers: [array([35.88461538, 31.46153846, 34.42307692]), array([80.        , 79.20833333, 78.29166667]), array([5.12, 5.84, 4.84])]
There are various kinds of clustering algorithms implemented in MLlib. Bisecting K-Means Clustering is another popular method.
# Applying Hierarchical Clustering
bkmeans = BisectingKMeans().setK(3)
bkmeans = bkmeans.setSeed(1)bkmodel = bkmeans.fit(vcluster_df)
bkcneters = bkmodel.clusterCenters()bkcneters[array([5.12, 5.84, 4.84]),
 array([35.88461538, 31.46153846, 34.42307692]),
 array([80.        , 79.20833333, 78.29166667])]
To read more about the clustering methods implemented in MLlib, follow the below link.
Classification Using PySpark
Classification is one of the widely used Machine algorithms and almost every data engineer and data scientist must know about these algorithms. Once the data is loaded and prepared, I will demonstrate three classification algorithms.
- NaiveBayes Classification
- Multi-Layer Perceptron Classification
- Decision Trees Classification
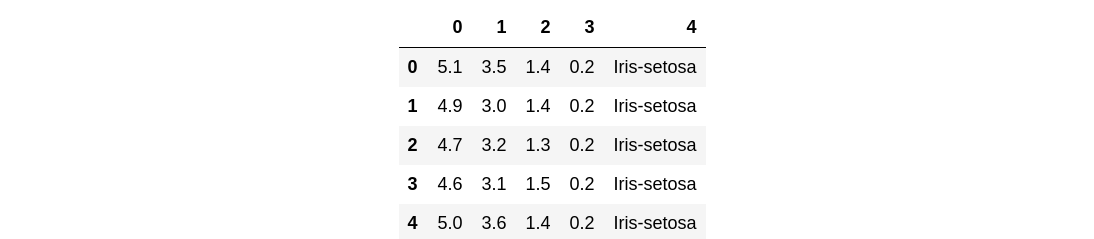
We explore the supervised classification algorithms using IRIS data. I have uploaded the data into my GitHub to reproduce the results. Users can download the data using the below command.
# Downloading the clustering data
!wget -q "https://raw.githubusercontent.com/amjadraza/blogs-data/master/spark_ml/iris.csv"df = pd.read_csv("https://raw.githubusercontent.com/amjadraza/blogs-data/master/spark_ml/iris.csv", header=None)df.head()
spark.createDataFrame(df, columns)DataFrame[c_0: double, c_1: double, c_2: double, c_3: double, c4 : string]
Preprocessing the Iris Data
In this section, we will be using the IRIS data to understand the classification. To perform ML models, we apply the preprocessing step on our input data.
from pyspark.sql.functions import *
from pyspark.ml.feature import VectorAssembler
from pyspark.ml.feature import  StringIndexer# Read the iris data
df_iris = pd.read_csv("https://raw.githubusercontent.com/amjadraza/blogs-data/master/spark_ml/iris.csv", header=None)
iris_df = spark.createDataFrame(df_iris)iris_df.show(5, False)+------------+-----------+------------+-----------+-----------+
|sepal_length|sepal_width|petal_length|petal_width|species    |
+------------+-----------+------------+-----------+-----------+
|5.1         |3.5        |1.4         |0.2        |Iris-setosa|
|4.9         |3.0        |1.4         |0.2        |Iris-setosa|
|4.7         |3.2        |1.3         |0.2        |Iris-setosa|
|4.6         |3.1        |1.5         |0.2        |Iris-setosa|
|5.0         |3.6        |1.4         |0.2        |Iris-setosa|
+------------+-----------+------------+-----------+-----------+
only showing top 5 rows# Rename the columns
iris_df = iris_df.select(col("0").alias("sepal_length"),
                         col("1").alias("sepal_width"),
                         col("2").alias("petal_length"),
                         col("3").alias("petal_width"),
                         col("4").alias("species"),
                        )# Converting the columns into features
vectorAssembler = VectorAssembler(inputCols = ["sepal_length", "sepal_width", "petal_length", "petal_width"],
                                  outputCol = "features")
viris_df = vectorAssembler.transform(iris_df)viris_df.show(5, False)+------------+-----------+------------+-----------+-----------+-----------------+
|sepal_length|sepal_width|petal_length|petal_width|species    |features         |
+------------+-----------+------------+-----------+-----------+-----------------+
|5.1         |3.5        |1.4         |0.2        |Iris-setosa|[5.1,3.5,1.4,0.2]|
|4.9         |3.0        |1.4         |0.2        |Iris-setosa|[4.9,3.0,1.4,0.2]|
|4.7         |3.2        |1.3         |0.2        |Iris-setosa|[4.7,3.2,1.3,0.2]|
|4.6         |3.1        |1.5         |0.2        |Iris-setosa|[4.6,3.1,1.5,0.2]|
|5.0         |3.6        |1.4         |0.2        |Iris-setosa|[5.0,3.6,1.4,0.2]|
+------------+-----------+------------+-----------+-----------+-----------------+
only showing top 5 rowsindexer = StringIndexer(inputCol="species", outputCol = "label")
iviris_df = indexer.fit(viris_df).transform(viris_df)iviris_df.show(2, False)+------------+-----------+------------+-----------+-----------+-----------------+-----+
|sepal_length|sepal_width|petal_length|petal_width|species    |features         |label|
+------------+-----------+------------+-----------+-----------+-----------------+-----+
|5.1         |3.5        |1.4         |0.2        |Iris-setosa|[5.1,3.5,1.4,0.2]|0.0  |
|4.9         |3.0        |1.4         |0.2        |Iris-setosa|[4.9,3.0,1.4,0.2]|0.0  |
+------------+-----------+------------+-----------+-----------+-----------------+-----+
only showing top 2 rows
Naive Bayes Classification
Once the data is prepared, we are ready to apply the first classification algorithm.
from pyspark.ml.classification import NaiveBayes
from pyspark.ml.evaluation import MulticlassClassificationEvaluator# Create the traing and test splits
splits = iviris_df.randomSplit([0.6,0.4], 1)
train_df = splits[0]
test_df = splits[1]# Apply the Naive bayes classifier
nb = NaiveBayes(modelType="multinomial")
nbmodel = nb.fit(train_df)
predictions_df = nbmodel.transform(test_df)predictions_df.show(1, False)+------------+-----------+------------+-----------+-----------+-----------------+-----+------------------------------------------------------------+------------------------------------------------------------+----------+
|sepal_length|sepal_width|petal_length|petal_width|species    |features         |label|rawPrediction                                               |probability                                                 |prediction|
+------------+-----------+------------+-----------+-----------+-----------------+-----+------------------------------------------------------------+------------------------------------------------------------+----------+
|4.3         |3.0        |1.1         |0.1        |Iris-setosa|[4.3,3.0,1.1,0.1]|0.0  |[-9.966434726497221,-11.294595492758821,-11.956012812323921]|[0.7134106367667451,0.18902823898426235,0.09756112424899269]|0.0       |
+------------+-----------+------------+-----------+-----------+-----------------+-----+------------------------------------------------------------+------------------------------------------------------------+----------+
only showing top 1 row
Let us Evaluate the trained classifier
evaluator = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
nbaccuracy = evaluator.evaluate(predictions_df)
nbaccuracy0.8275862068965517
Multilayer Perceptron Classification
The second classifier we will be investigating is a Multi-layer perceptron. In this tutorial, I am not going into details of the optimal MLP network for this problem however in practice, you research the optimal network suitable to the problem in hand.
from pyspark.ml.classification import MultilayerPerceptronClassifier# Define the MLP Classifier
layers = [4,5,5,3]
mlp = MultilayerPerceptronClassifier(layers = layers, seed=1)
mlp_model = mlp.fit(train_df)
mlp_predictions = mlp_model.transform(test_df)# Evaluate the MLP classifier
mlp_evaluator = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
mlp_accuracy = mlp_evaluator.evaluate(mlp_predictions)
mlp_accuracy0.9827586206896551
Decision Trees Classification
Another common classifier in the ML family is the Decision Tree Classifier, in this section, we explore this classifier.
from pyspark.ml.classification import DecisionTreeClassifier# Define the DT Classifier
dt = DecisionTreeClassifier(labelCol="label", featuresCol="features")
dt_model = dt.fit(train_df)
dt_predictions = dt_model.transform(test_df)# Evaluate the DT Classifier
dt_evaluator = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
dt_accuracy = dt_evaluator.evaluate(dt_predictions)
dt_accuracy0.9827586206896551
Apart from the above three demonstrated classification algorithms, Spark MLlib has also many other implementations of classification algorithms. Details of the implemented classification algorithms can be found at below link
It is highly recommended to try some of the classification algorithms to get hands-on.
Regression using PySpark
In this section, we explore the Machine learning models for regression problems using pyspark. Regression models are helpful in predicting future values using past data.
We will use the Combined Cycle Power Plant data set to predict the net hourly electrical output (EP). I have uploaded the data to my GitHub so that users can reproduce the results.
from pyspark.ml.regression import LinearRegression
from pyspark.ml.feature import VectorAssembler# Read the iris data
df_ccpp = pd.read_csv("https://raw.githubusercontent.com/amjadraza/blogs-data/master/spark_ml/ccpp.csv")
pp_df = spark.createDataFrame(df_ccpp)pp_df.show(2, False)+-----+-----+-------+-----+------+
|AT   |V    |AP     |RH   |PE    |
+-----+-----+-------+-----+------+
|14.96|41.76|1024.07|73.17|463.26|
|25.18|62.96|1020.04|59.08|444.37|
+-----+-----+-------+-----+------+
only showing top 2 rows# Create the feature column using VectorAssembler class
vectorAssembler = VectorAssembler(inputCols =["AT", "V", "AP", "RH"], outputCol = "features")
vpp_df = vectorAssembler.transform(pp_df)vpp_df.show(2, False)+-----+-----+-------+-----+------+---------------------------+
|AT   |V    |AP     |RH   |PE    |features                   |
+-----+-----+-------+-----+------+---------------------------+
|14.96|41.76|1024.07|73.17|463.26|[14.96,41.76,1024.07,73.17]|
|25.18|62.96|1020.04|59.08|444.37|[25.18,62.96,1020.04,59.08]|
+-----+-----+-------+-----+------+---------------------------+
only showing top 2 rows
Linear Regression
We start with the simplest regression technique i.e. Linear Regression.
# Define and fit Linear Regression
lr = LinearRegression(featuresCol="features", labelCol="PE")
lr_model = lr.fit(vpp_df)# Print and save the Model output
lr_model.coefficients
lr_model.intercept
lr_model.summary.rootMeanSquaredError4.557126016749486#lr_model.save()
Decision Tree Regression
In this section, we explore the Decision Tree Regression commonly used in Machine learning.
from pyspark.ml.regression import DecisionTreeRegressor
from pyspark.ml.evaluation import RegressionEvaluatorvpp_df.show(2, False)+-----+-----+-------+-----+------+---------------------------+
|AT   |V    |AP     |RH   |PE    |features                   |
+-----+-----+-------+-----+------+---------------------------+
|14.96|41.76|1024.07|73.17|463.26|[14.96,41.76,1024.07,73.17]|
|25.18|62.96|1020.04|59.08|444.37|[25.18,62.96,1020.04,59.08]|
+-----+-----+-------+-----+------+---------------------------+
only showing top 2 rows# Define train and test data split
splits = vpp_df.randomSplit([0.7,0.3])
train_df = splits[0]
test_df = splits[1]# Define the Decision Tree Model
dt = DecisionTreeRegressor(featuresCol="features", labelCol="PE")
dt_model = dt.fit(train_df)
dt_predictions = dt_model.transform(test_df)dt_predictions.show(1, False)+----+-----+-------+-----+------+--------------------------+-----------------+
|AT  |V    |AP     |RH   |PE    |features                  |prediction       |
+----+-----+-------+-----+------+--------------------------+-----------------+
|3.31|39.42|1024.05|84.31|487.19|[3.31,39.42,1024.05,84.31]|486.1117703349283|
+----+-----+-------+-----+------+--------------------------+-----------------+
only showing top 1 row# Evaluate the Model
dt_evaluator = RegressionEvaluator(labelCol="PE", predictionCol="prediction", metricName="rmse")
dt_rmse = dt_evaluator.evaluate(dt_predictions)
print("The RMSE of Decision Tree regression Model is {}".format(dt_rmse))The RMSE of Decision Tree regression Model is 4.451790078736588
Gradient Boosting Decision Tree Regression
Gradient Boosting is another common choice among ML professionals. Let us try the GBM in this section.
from pyspark.ml.regression import GBTRegressor# Define the GBT Model
gbt = GBTRegressor(featuresCol="features", labelCol="PE")
gbt_model = gbt.fit(train_df)
gbt_predictions = gbt_model.transform(test_df)# Evaluate the GBT Model
gbt_evaluator = RegressionEvaluator(labelCol="PE", predictionCol="prediction", metricName="rmse")
gbt_rmse = gbt_evaluator.evaluate(gbt_predictions)
print("The RMSE of GBT Tree regression Model is {}".format(gbt_rmse))The RMSE of GBT Tree regression Model is 4.035802933864555
Apart from the above-demonstrated regression algorithms, Spark MLlib has also many other implementations of regression algorithms. Details of the implemented regression algorithms can be found at the below link.
It is highly recommended to try some of the regression algorithms to get hands-on and play with the parameters.
A working Google Colab
Conclusions
In this tutorial, I have tried to give the readers an opportunity to learn and implement basic Machine Learning algorithms using PySpark. Spark not only provide the benefit of distributed processing but also can handle a large amount of data to be processing. To summarise, we have covered below topics/algorithms
- Setting up the Spark 3.0.1 in Google Colab
- Overview of Data Transformations using PySpark
- Clustering algorithms using PySpark
- Classification problems using PySpark
- Regression Problems using PySpark
References Readings/Links
- https://spark.apache.org/docs/latest/ml-features.html
- https://spark.apache.org/docs/3.0.1/ml-classification-regression.html#regression
- https://spark.apache.org/docs/3.0.1/ml-clustering.html
- https://spark.apache.org/docs/3.0.1/ml-classification-regression.html#classification
A comprehensive Guide: Machine Learning with Spark
Machine learning is getting popular in solving real-world problems in almost every business domain. It helps solve the problems using the data which is often unstructured, noisy, and in huge size. With the increase in data sizes and various sources of data, solving formulating and machine learning problems using standard techniques pose a big challenge. Spark is a distributed processing engine using the MapReduce framework to solve problems related to big data and processing of it.
Spark framework has its own machine learning module called MLlib. In this article, I will use pyspark and spark MLlib to demonstrate the use of machine learning using distributed processing. Readers will be able to learn the below concept with real examples.
- Setting up Spark in the Google Colaboratory
- Machine Learning Basic Concepts
- Preprocessing and Data Transformation using Spark
- Spark Clustering with pyspark
- Classification with pyspark
- Regression methods with pyspark
A working google colab notebook will be provided to reproduce the results.
Since this article is a hands-on tutorial covering the transformations, classification, clustering, and regression using pyspark in one session, the length of the article is longer than my previous articles. One benefit is that you can go through the basic concepts and implementation in one go.
Setting up Spark 3.0.1 in the Google Colaboratory
As a first step, I configure the google colab runtime with spark installation. For details, readers may read my article Getting Started Spark 3.0.0 in Google Colab om medium.
We will install below programs
- Java 8
- spark-3.0.1
- Hadoop3.2
- Findspark
you can install the LATEST version of Spark using below set of commands.
Environment Variable
After installing the spark and Java, set the enviroment variables where Spark and Java are installed.
Spark Installation test
Lets test the installation of spark in our google colab environment.
/content/spark-3.0.1-bin-hadoop3.2/python/pyspark/sql/session.py:381: UserWarning: inferring schema from dict is deprecated,please use pyspark.sql.Row instead
  warnings.warn("inferring schema from dict is deprecated,"
+-----+
|hello|
+-----+
|world|
|world|
|world|
+-----+
only showing top 3 rows
3.0.1
Machine Learning
Once, we have set up the spark in google colab and made sure it is running with the correct version i.e. 3.0.1 in this case, we can start exploring the machine learning API developed on top of Spark. Pyspark is a higher level of API to use spark with python. For this tutorial, I assume the readers have a basic understanding of Machine learning and used SK-Learn for model building and training. Spark MLlib used the same fit and predict structure as in SK-Learn.
In order to reproduce the results, I have uploaded the data to my GitHub and can be accessed easily.
Learn by Doing: Use the colab notebook to run it yourself
Data Preparation and Transformations in Spark
This section covers the basic steps involved in transformations of input feature data into the format Machine Learning algorithms accept. We will be covering the transformations coming with the SparkML library. To understand or read more about the available spark transformations in 3.0.3, follow the below link.
Normalize Numeric Data
MinMaxScaler is one of the favorite classes shipped with most machine learning libraries. It scaled the data between 0 and 1.
+---+------------------+
| id|          features|
+---+------------------+
|  1|[10.0,10000.0,1.0]|
|  2|[20.0,30000.0,2.0]|
|  3|[30.0,40000.0,3.0]|
+---+------------------+
+---+------------------+--------------------+
| id|          features|           sfeatures|
+---+------------------+--------------------+
|  1|[10.0,10000.0,1.0]|           (3,[],[])|
|  2|[20.0,30000.0,2.0]|[0.5,0.6666666666...|
|  3|[30.0,40000.0,3.0]|       [1.0,1.0,1.0]|
+---+------------------+--------------------+
Standardize Numeric Data
StandardScaler is another well-known class written with machine learning libraries. It normalizes the data between -1 and 1 and converts the data into bell-shaped data. You can demean the data and scale to some variance.
+---+------------------+--------------------+
| id|          features|           sfeatures|
+---+------------------+--------------------+
|  1|[10.0,10000.0,1.0]|[-1.0,-1.09108945...|
|  2|[20.0,30000.0,2.0]|[0.0,0.2182178902...|
|  3|[30.0,40000.0,3.0]|[1.0,0.8728715609...|
+---+------------------+--------------------+
Bucketize Numeric Data
The real data sets come with various ranges and sometimes it is advisable to transform the data into well-defined buckets before plugging into machine learning algorithms.
Bucketizer class is handy to transform the data into various buckets.
+--------+
|features|
+--------+
|  -800.0|
|   -10.5|
|    -1.7|
|     0.0|
|     8.2|
|    90.1|
+--------+
+--------+---------+
|features|bfeatures|
+--------+---------+
|  -800.0|      0.0|
|   -10.5|      0.0|
|    -1.7|      1.0|
|     0.0|      2.0|
|     8.2|      2.0|
|    90.1|      3.0|
+--------+---------+
Tokenize text Data
Natural Language Processing is one of the main applications of Machine learning. One of the first steps for NLP is tokenizing the text into words or token. We can utilize the Tokenizer class with SparkML to perform this task.
+---+--------------------+
| id|           sentences|
+---+--------------------+
|  1|This is an introd...|
|  2|Mlib incluse libr...|
|  3|It also incluses ...|
+---+--------------------+
[Row(id=1, sentences='This is an introduction to sparkMlib', words=['this', 'is', 'an', 'introduction', 'to', 'sparkmlib']),
 Row(id=2, sentences='Mlib incluse libraries fro classfication and regression', words=['mlib', 'incluse', 'libraries', 'fro', 'classfication', 'and', 'regression']),
 Row(id=3, sentences='It also incluses support for data piple lines', words=['it', 'also', 'incluses', 'support', 'for', 'data', 'piple', 'lines'])]
TF-IDF
Term frequency-inverse document frequency (TF-IDF) is a feature vectorization method widely used in text mining to reflect the importance of a term to a document in the corpus. Using the above-tokenized data, Let us apply the TF-IDF
[Row(id=1, sentences='This is an introduction to sparkMlib', words=['this', 'is', 'an', 'introduction', 'to', 'sparkmlib'], rawfeatures=SparseVector(20, {6: 2.0, 8: 1.0, 9: 1.0, 10: 1.0, 13: 1.0}))][Row(id=1, sentences='This is an introduction to sparkMlib', words=['this', 'is', 'an', 'introduction', 'to', 'sparkmlib'], rawfeatures=SparseVector(20, {6: 2.0, 8: 1.0, 9: 1.0, 10: 1.0, 13: 1.0}), idffeatures=SparseVector(20, {6: 0.5754, 8: 0.6931, 9: 0.0, 10: 0.6931, 13: 0.2877}))]User can play with various transformations depending on the requirements of the problem in-hand.
Clustering Using PySpark
Clustering is a machine learning technique where the data is grouped into a reasonable number of classes using the input features. In this section, we study the basic application of clustering techniques using the spark ML framework.
Load the clustering data stored in csv format using spark
Convert the tabular data into vectorized format using VectorAssembler
+----+----+----+--------------+
|col1|col2|col3|      features|
+----+----+----+--------------+
|   7|   4|   1| [7.0,4.0,1.0]|
|   7|   7|   9| [7.0,7.0,9.0]|
|   7|   9|   6| [7.0,9.0,6.0]|
|   1|   6|   5| [1.0,6.0,5.0]|
|   6|   7|   7| [6.0,7.0,7.0]|
|   7|   9|   4| [7.0,9.0,4.0]|
|   7|  10|   6|[7.0,10.0,6.0]|
|   7|   8|   2| [7.0,8.0,2.0]|
|   8|   3|   8| [8.0,3.0,8.0]|
|   4|  10|   5|[4.0,10.0,5.0]|
+----+----+----+--------------+
only showing top 10 rows
Once the data is prepared into the format MLlib can use for models, now we can define and train the clustering algorithm such as K-Means. We can define the number of clusters and initialize the seed as done below.
After training has been finished, let us print the centers.
The location of centers: [array([35.88461538, 31.46153846, 34.42307692]), array([80. , 79.20833333, 78.29166667]), array([5.12, 5.84, 4.84])]
There are various kind of clustering algorithms implemented in MLlib. Bisecting K-Means Clustering is another popular method.
[array([5.12, 5.84, 4.84]),
 array([35.88461538, 31.46153846, 34.42307692]),
 array([80.        , 79.20833333, 78.29166667])]
To read more about the clustering methods implemented in MLlib, follow below link. https://spark.apache.org/docs/3.0.1/ml-clustering.html
Classification Using PySpark
Classification is one of the widely used Machine algorithms and almost every data engineer and data scientist must know about these algorithms. Once the data is loaded and prepared, I will demonstrate three classification algorithms.
- NaiveBayes Classification
- Multi-Layer Perceptron Classification
- Decision Trees Classification
We explore the supervised classification algorithms using IRIS data. I have uploaded the data into my GitHub to reproduce the results. Users can download the data using below command.
| 0 | 1 | 2 | 3 | 4 | |
|---|---|---|---|---|---|
| 0 | 5.1 | 3.5 | 1.4 | 0.2 | Iris-setosa |
| 1 | 4.9 | 3.0 | 1.4 | 0.2 | Iris-setosa |
| 2 | 4.7 | 3.2 | 1.3 | 0.2 | Iris-setosa |
| 3 | 4.6 | 3.1 | 1.5 | 0.2 | Iris-setosa |
| 4 | 5.0 | 3.6 | 1.4 | 0.2 | Iris-setosa |
DataFrame[c_0: double, c_1: double, c_2: double, c_3: double, c4 : string]
Preprocessing the Iris Data
In this section, we will be using the IRIS data to understand the classification. To perform ML models, we apply the preprocessing step on our input data.
+------------+-----------+------------+-----------+-----------+
|sepal_length|sepal_width|petal_length|petal_width|species    |
+------------+-----------+------------+-----------+-----------+
|5.1         |3.5        |1.4         |0.2        |Iris-setosa|
|4.9         |3.0        |1.4         |0.2        |Iris-setosa|
|4.7         |3.2        |1.3         |0.2        |Iris-setosa|
|4.6         |3.1        |1.5         |0.2        |Iris-setosa|
|5.0         |3.6        |1.4         |0.2        |Iris-setosa|
+------------+-----------+------------+-----------+-----------+
only showing top 5 rows
+------------+-----------+------------+-----------+-----------+-----------------+
|sepal_length|sepal_width|petal_length|petal_width|species    |features         |
+------------+-----------+------------+-----------+-----------+-----------------+
|5.1         |3.5        |1.4         |0.2        |Iris-setosa|[5.1,3.5,1.4,0.2]|
|4.9         |3.0        |1.4         |0.2        |Iris-setosa|[4.9,3.0,1.4,0.2]|
|4.7         |3.2        |1.3         |0.2        |Iris-setosa|[4.7,3.2,1.3,0.2]|
|4.6         |3.1        |1.5         |0.2        |Iris-setosa|[4.6,3.1,1.5,0.2]|
|5.0         |3.6        |1.4         |0.2        |Iris-setosa|[5.0,3.6,1.4,0.2]|
+------------+-----------+------------+-----------+-----------+-----------------+
only showing top 5 rows
+------------+-----------+------------+-----------+-----------+-----------------+-----+
|sepal_length|sepal_width|petal_length|petal_width|species    |features         |label|
+------------+-----------+------------+-----------+-----------+-----------------+-----+
|5.1         |3.5        |1.4         |0.2        |Iris-setosa|[5.1,3.5,1.4,0.2]|0.0  |
|4.9         |3.0        |1.4         |0.2        |Iris-setosa|[4.9,3.0,1.4,0.2]|0.0  |
+------------+-----------+------------+-----------+-----------+-----------------+-----+
only showing top 2 rows
Naive Bayes Calssification
Once the data is prepared, we are ready to apply the first classification algorithm.
+------------+-----------+------------+-----------+-----------+-----------------+-----+------------------------------------------------------------+------------------------------------------------------------+----------+
|sepal_length|sepal_width|petal_length|petal_width|species    |features         |label|rawPrediction                                               |probability                                                 |prediction|
+------------+-----------+------------+-----------+-----------+-----------------+-----+------------------------------------------------------------+------------------------------------------------------------+----------+
|4.3         |3.0        |1.1         |0.1        |Iris-setosa|[4.3,3.0,1.1,0.1]|0.0  |[-9.966434726497221,-11.294595492758821,-11.956012812323921]|[0.7134106367667451,0.18902823898426235,0.09756112424899269]|0.0       |
+------------+-----------+------------+-----------+-----------+-----------------+-----+------------------------------------------------------------+------------------------------------------------------------+----------+
only showing top 1 row
Let us Evaluate the trained classifier
0.8275862068965517
Multilayer Perceptron Classification
The second classifier we will be investigating is a Multi-layer perceptron. In this tutorial, I am not going into details of the optimal MLP network for this problem however in practice, you research the optimal network suitable to the problem in hand.
0.9827586206896551
Decision Trees Classification
Another common classifier in the ML family is the Decision Tree Classifier, in this section, we explore this classifier.
0.9827586206896551
Apart from the above three demonstrated classification algorithms, Spark MLlib has also many other implementations of classification algorithms. Details of the implemented classification algorithms can be found at below link.
https://spark.apache.org/docs/3.0.1/ml-classification-regression.html#classification
It is highly recommended to try some of the classification algorithms to get hands-on.
Regression using PySpark
In this section, we explore the Machine learning models for regression problems using pyspark.Regression models are helpful in predicting the future values using the past data.
We will use the Combined Cycle Power Plant data set to predict the net hourly electrical output (EP). I have uploaded the data to my GitHub so that users can reproduce the results.
+-----+-----+-------+-----+------+
|AT   |V    |AP     |RH   |PE    |
+-----+-----+-------+-----+------+
|14.96|41.76|1024.07|73.17|463.26|
|25.18|62.96|1020.04|59.08|444.37|
+-----+-----+-------+-----+------+
only showing top 2 rows
+-----+-----+-------+-----+------+---------------------------+
|AT   |V    |AP     |RH   |PE    |features                   |
+-----+-----+-------+-----+------+---------------------------+
|14.96|41.76|1024.07|73.17|463.26|[14.96,41.76,1024.07,73.17]|
|25.18|62.96|1020.04|59.08|444.37|[25.18,62.96,1020.04,59.08]|
+-----+-----+-------+-----+------+---------------------------+
only showing top 2 rows
Linear Regression
We start with simplest regression technique i.e. Linear Regression.
4.557126016749486
Decision Tree Regression
In thsi section, we explore the Decision Tree Regression commonly used in Machine learning.
+-----+-----+-------+-----+------+---------------------------+
|AT   |V    |AP     |RH   |PE    |features                   |
+-----+-----+-------+-----+------+---------------------------+
|14.96|41.76|1024.07|73.17|463.26|[14.96,41.76,1024.07,73.17]|
|25.18|62.96|1020.04|59.08|444.37|[25.18,62.96,1020.04,59.08]|
+-----+-----+-------+-----+------+---------------------------+
only showing top 2 rows
+----+-----+-------+-----+------+--------------------------+-----------------+
|AT  |V    |AP     |RH   |PE    |features                  |prediction       |
+----+-----+-------+-----+------+--------------------------+-----------------+
|3.31|39.42|1024.05|84.31|487.19|[3.31,39.42,1024.05,84.31]|486.1117703349283|
+----+-----+-------+-----+------+--------------------------+-----------------+
only showing top 1 row
The RMSE of Decision Tree regression Model is 4.451790078736588
Gradient Boosting Decision Tree Regression
Gradient Boosting is another common choice among ML professionals. Let us try the GBM in this section.
The RMSE of GBT Tree regression Model is 4.035802933864555
Apart from the above-demonstrated regression algorithms, Spark MLlib has also many other implementations of regression algorithms. Details of the implemented regression algorithms can be found at the below link.
https://spark.apache.org/docs/3.0.1/ml-classification-regression.html#regression
It is highly recommended to try some of the regression algorithms to get hands-on and play with the parameters.
Conclusions
In this tutorial, I have tried to give the readers an opportunity to learn and implement basic Machine Learning algorithms using PySpark. Spark not only provide the benefit of distributed processing but also can handle a large amount of data to be processing. To summarise, we have covered below topics/algorithms
- Setting up the spark 3.0.1 in Google Colab
- Overview of Data Transformations using PySpark
- Clustering algorithms using PySpark
- Classification problems using PySpark
- Regression Problems using PySpark